On behalf of the Nominating Committee, I’m pleased to share the slate of candidates for the 2026 board election. Every active member organisation is invited to submit a ballot to elect the incoming board class.
We’re providing a summary of the board’s July 2026 meeting. The July board meeting is our only in-person meeting. The board gathers for two days of strategic thinking and long-range planning, as well as conducting annual board business. This year, we focused on allocating surplus funds we have on hand to invest in a three-year project to redesign the content system. In a related discussion, we decided to lower content registration fees starting in 2027 because we’ve had a demonstrated history of generating surpluses, exceeding what we need to run Crossref. We also discussed the board structure, as part of our regular review of stakeholder governance. And we conducted annual board business, such as approving the audited financial statements and reviewed our risk register and mitigation plans.
The resolutions are available on the dedicated section of our website, which also lists the members of the Board and offers further information about our governance.
We also managed to squeeze in watching a World Cup game over dinner.
Starting today, funder names deposited in Crossref metadata without an identifier will be matched to ROR IDs, to support an open and connected Research Nexus. Funding information is an increasingly important part of the scholarly record. The improved matching strategy supports researchers, funders, institutions, and meta-researchers, who rely on that information to understand how research is supported and what outcomes that support produces.
Strengthening Scholarly Publishing in Africa is a collaborative webinar series bringing together ASSAf, Crossref, DOAJ, EIFL, and PKP to share practical guidance, resources, and approaches for strengthening the publishing ecosystem in the region. This series responds to the growing interest in open access, digital publishing, stronger editorial practices, and greater visibility of research publishing across Africa. Each partner organisation has long experience of building that capacity in the area of their expertise. In this series, we’re coming together to offer a more holistic learning experience to the community of African publishers, putting different aspects of the publishing process in their broader context.
ROR IDs as affiliations of authors can now be tracked in Participation Reports! Check your own Participation Report to see how many of your publications have author or grantee affiliations as ROR IDs in our metadata. If you deposit metadata via XML, see our guide on affiliations and ROR for instructions on how to include affiliations and ROR IDs in your metadata.
We encourage our members to include ROR IDs in metadata in order to help make research organisation information clear and consistent as it is shared between systems. ROR IDs are essential to realise a rich and complete Research Nexus because they enable connections between research outputs and the organisations that support researchers.
“At Scholastica, we care about taking steps to enrich metadata – like adding ROR IDs, for example, on behalf of our customers, so they don’t have to worry about the technical aspects of metadata collection or creation and can instead focus on maximizing the discovery benefits.” – Cory Schires, Co-founder and Chief Technology Officer, Scholastica
“If we’re talking about misconduct, then you might need to be able to contact the institution that the author is from. On an individual manuscript, it doesn’t matter if there’s no identifier – an address will do. But if you find some signal that is on manuscripts at scale, and you’ve got thousands of them, well, you need an identifier. You can’t go through them and try and search for every single one of those institutions.” – Adam Day, CEO, Clear Skies Ltd.
ROR IDs are specifically designed to be implemented in any system that captures institutional affiliations and to enable a richer networked research infrastructure. ROR IDs are interoperable with other organisation identifiers, including GRID (which provided the seed data that ROR launched with), the Open Funder Registry, ISNI, and Wikidata. ROR data is available under a CC0 Public Domain waiver and can be accessed at no cost via our public API and a data dump.
ROR is part of the open infrastructure we help run—not a separate organisation you need to deal with elsewhere. We co-founded it and operate it jointly with DataCite and the California Digital Library, and we launched it with seed data from GRID from Digital Science. Together we’ve invested in building an open registry of research organisation identifiers that can be embedded in scholarly infrastructure to link research to organisations effectively. ROR is not a membership organisation (or an independent legal entity at all!), and we charge no fees for use of the registry or the API. In fact, much of ROR’s day-to-day work is carried out by Crossref staff: as well as bringing 40% of its costs in-house following our board’s decision in 2022, we lead ROR’s community engagement and communications, its metadata curation and technical support, and its financial administration—holding ROR’s shared funds and running its bookkeeping and annual audit. The terms of this shared stewardship are set out in our Memorandum of Agreement (PDF).
Dedicated ROR staffing (2024): Crossref 2.1 FTE, DataCite 1.1 FTE, California Digital Library 0.75 FTE.
Why ROR IDs are an important element of our metadata
For a long time, we only collected affiliation metadata as free-text strings, which made for ambiguity and incomplete data. An author affiliated with the University of California at Berkeley might give the name of the university in any of several common ways:
University of California, Berkeley
University of California at Berkeley
University of California Berkeley
UC Berkeley
Berkeley
And likely more …
While it isn’t too difficult for a human to guess that “UC Berkeley,” “University of California, Berkeley,” and “University of California at Berkeley” are all referring to the same university, a machine interpreting this information wouldn’t necessarily make the same inference. If you are trying to easily find all of the publications associated with UC Berkeley, you would need to run and reconcile multiple searches at best, or, at worst, miss some data completely.
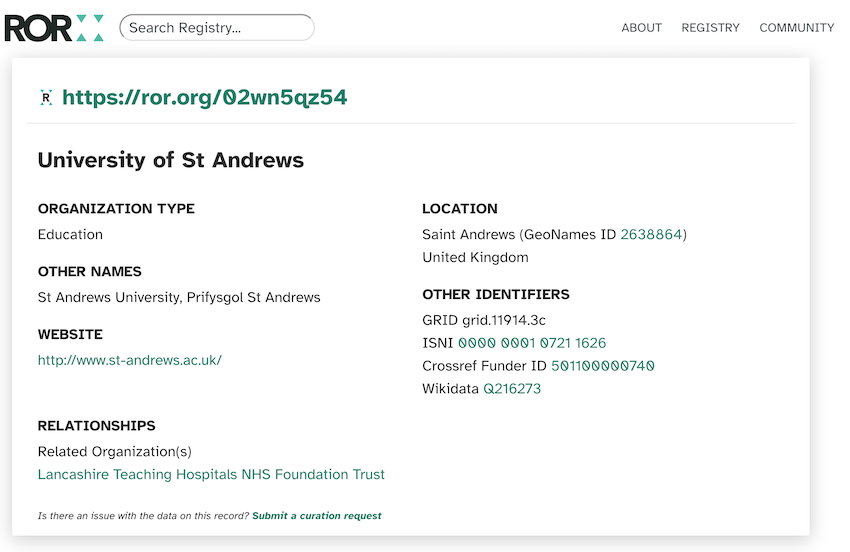
This is where an organisation identifier comes in: a single, unambiguous, standardised identifier that will always stay the same. For UC Berkeley, that would be https://ror.org/01an7q238.
In 2019, our members indicated that the ability to associate research outputs with organisations in a clean and consistent fashion was one of their most desired improvements to our metadata. In January of 2022, therefore, we added support for ROR IDs in our metadata schema and APIs. Since then, more and more members have been including ROR IDs in their metadata.
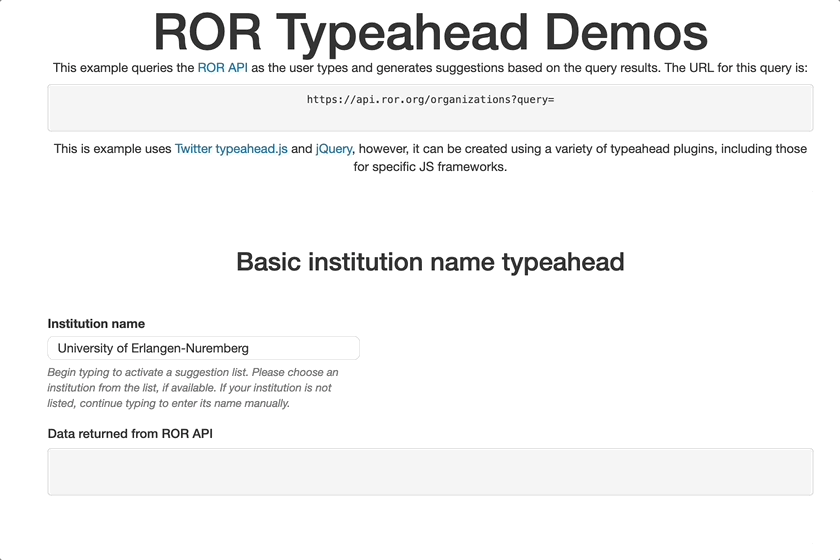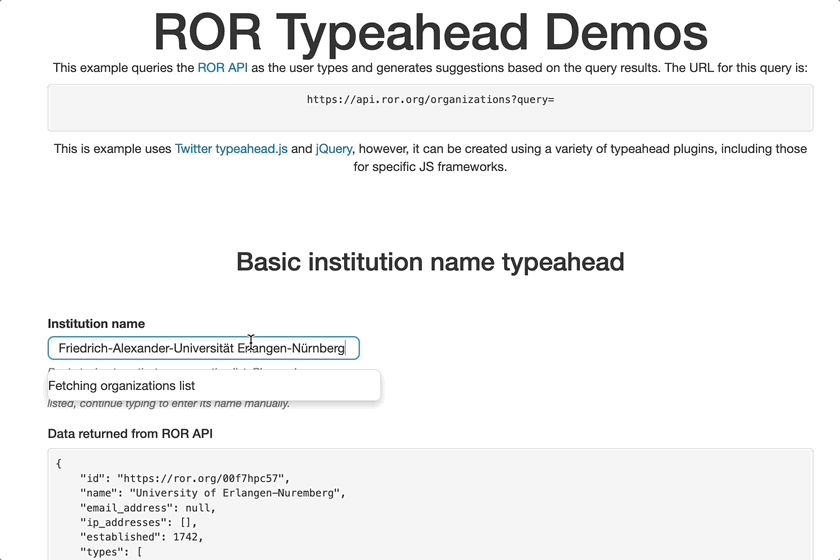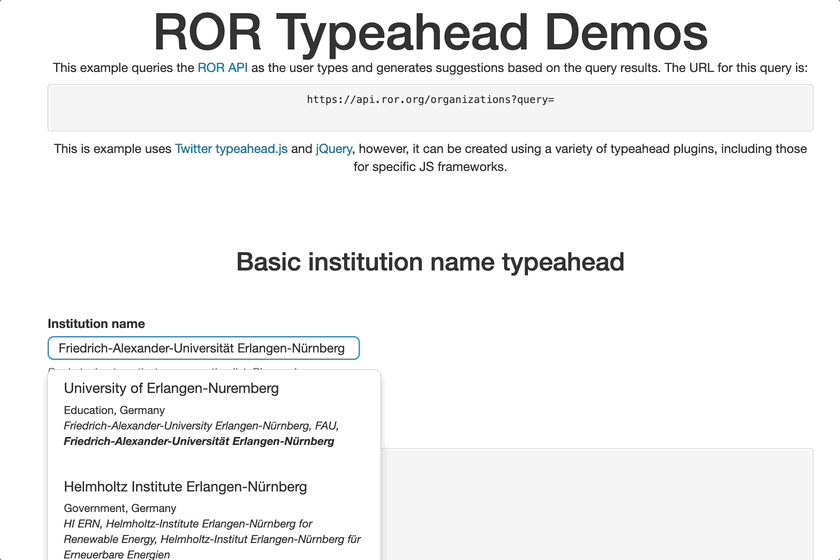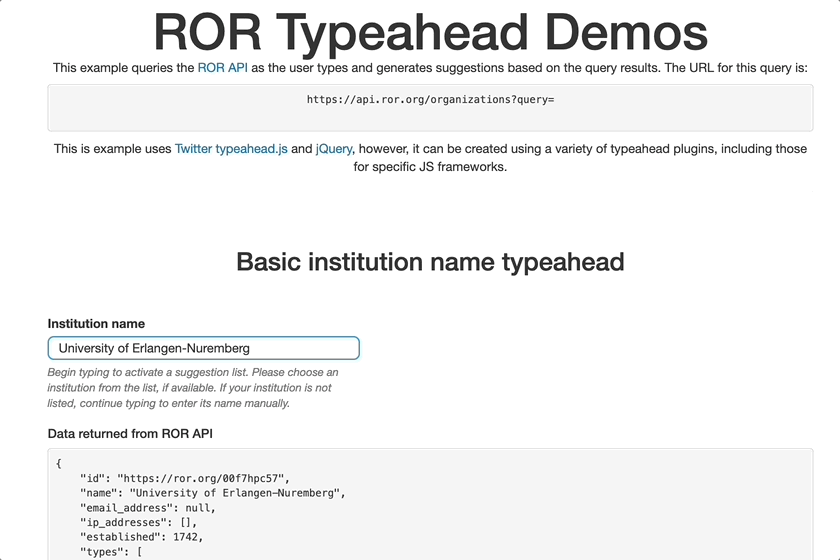
Publishers and service providers can implement ROR in their systems so that submitting authors and co-authors can easily choose their affiliation from a ROR-powered list instead of typing in free text. Authors themselves do not have to provide a ROR ID or even know that a ROR ID is being collected. This affiliation information can then be sent to us alongside other publication information.
Demo of collecting ROR IDs in a typeahead field
If the submission system you use does not yet support ROR, or if you don’t use a submission system, you’ll still be able to provide ROR IDs in your metadata. ROR IDs can be added to JATS XML, and our helper tools will start to support the deposit of ROR IDs. There’s also an OpenRefine reconciler that can map your internal identifiers to ROR identifiers.
ROR IDs for affiliations stand to transform the usability of our metadata. While it’s crucial to have IDs for affiliations, it’s equally important that the affiliation data can be easily used. The ROR dataset is CC0, so ROR IDs and associated affiliation data can be freely and openly used and reused without any restrictions.
The ROR IDs registered by members in their metadata are available via our open APIs so that they can be detected, analysed, and reused by anyone interested in linking research outputs to research organisations. Examples include:
Institutions who want to monitor and measure their research output by the articles their researchers have published
Funders who want to be able to discover and track the research and researchers they have supported
Academic librarians who want to find all of the publications associated with their campus
Journals who want to know where authors are affiliated so they can determine eligibility for institutionally sponsored publishing agreements
The inclusion of ROR IDs in our metadata will eventually help all these entities make all these connections much more easily.
Get ready to ROR 🦁!
ROR is already working with publishers, funders and service providers who are integrating ROR in their systems, mapping their affiliation data to ROR IDs, and/or including ROR IDs in publication metadata. Libraries and institutional repositories are also beginning to build ROR into their systems and to send ROR IDs to us in their metadata. See the growing list of active and in-progress ROR integrations for more stakeholders who are supporting ROR.
If you deposit metadata with us via XML, see our guide on Affiliations and ROR for instructions on how to include author affiliations and ROR IDs.
For further information on how ROR IDs are supported in our metadata, you can take a look at this .xsd file (under the ‘institution’ element) or in this journal article example XML. ROR also has some great help documentation for publishers and anyone else working with the ROR Registry.
Get in touch with us if you have questions about ROR, want to add ROR IDs to your metadata, or otherwise get more involved. You can also ask any questions on our community forum.